Delivery driver: timed captions
The recogniser's output with timings, 6 cues over the full take. Carries the same normalisation as the plain transcript in this group, so it inherits the same scoring trap, and adds the timing dimension: a cue that starts before the word is spoken is a different defect from a cue with the wrong words in it.
srt
application/x-subrip
- Utterance
- delivery-driver
- Voice
- am_adam
- Speech Rate
- 1.05
- Synthetic
- true
- Disclosure
- Synthetic speech. Generated locally with a text-to-speech model from an authored script; not a recording of a real person, and no real customer, order or incident is described.
- Schema Version
- 1
Binary srt: no in-browser preview. Download it above to open in a compatible application.
Specifications
- Utterance
- delivery-driver
- Voice
- am_adam
- Speech Rate
- 1.05
- Synthetic
- true
- Disclosure
- Synthetic speech. Generated locally with a text-to-speech model from an authored script; not a recording of a real person, and no real customer, order or incident is described.
- Schema Version
- 1
- Role
- asr-captions
- Cues
- 6
Testing contract
Expected to pass- Scenario
- Parse the cues and check they are ordered, non-overlapping and inside the audio.
- Expected result
- Every cue parses with a start before its end, no two cues overlap, and the last cue ends within the its recorded length of the full take in this group.
What is a .srt file?
SRT (SubRip) is a plain-text subtitle format listing numbered cues, each with a start and end timecode and one or more lines of text. It is simple, human-readable, and extremely widely supported by players. It carries no styling metadata beyond basic inline tags.
How to use this file
Use an example SRT to test subtitle parsing, timecode handling, and converters that translate between SRT and WebVTT or other caption formats.
How to use this file for testing
“Delivery driver: timed captions” is a deterministic Novus Examples fixture for ASR testing, Media accessibility. Short synthetic digit/tone utterances with transcript JSON and clean↔noise pairs, for testing ASR loaders, WER harnesses, and audio preprocessing.
Documented properties for this file: asr-captions · 6 cues. Compare results against paired or grouped companions on this page when present (clean↔damaged, searchable↔scanned, or format twins) so scores stay reproducible across runs.
Download the file once, keep the path stable in CI or local scripts, and treat the spec table as the contract: dimensions, seeds, field lists, and roles are intentional. Corrupt or invalid samples are labelled as such, expect parsers to fail loudly rather than silently accept them.
Media fixtures are short and synthetic by design. Prefer waveform or transcript ground truth in the same group when measuring ASR, trim, upscale, or sync tools; do not assume broadcast-quality masters.
Run ASR on the clip and score the transcript against the documented ground-truth script; clips are short, synthetic, and read from a fixed word or digit sequence.
Code examples
<video controls src="clip.mp4">
  <track kind="captions" srclang="en" label="English" src="captions.asr.srt" default>
</video>
Related files
- srtComplaint call: timed captionsThe recogniser's output with timings, 4 cues over the full take. Carries the same normalisation as the plain transcript in this group, so it inherits the same scoring trap, and adds the timing dimension: a cue that starts before the word is spoken is a different defect from a cue with the wrong words in it.
- srtCost podcast: timed captionsThe recogniser's output with timings, 4 cues over the full take. Carries the same normalisation as the plain transcript in this group, so it inherits the same scoring trap, and adds the timing dimension: a cue that starts before the word is spoken is a different defect from a cue with the wrong words in it.
- srtHaccp training: timed captionsThe recogniser's output with timings, 4 cues over the full take. Carries the same normalisation as the plain transcript in this group, so it inherits the same scoring trap, and adds the timing dimension: a cue that starts before the word is spoken is a different defect from a cue with the wrong words in it.
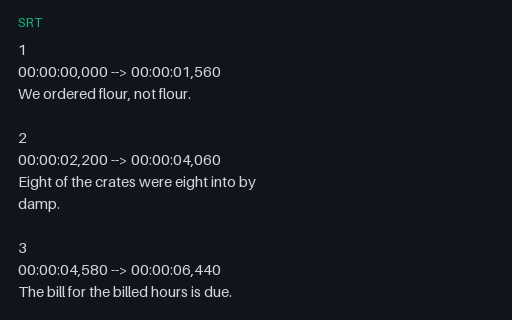
- srtHomophone stress: timed captionsThe recogniser's output with timings, 5 cues over the full take. Carries the same normalisation as the plain transcript in this group, so it inherits the same scoring trap, and adds the timing dimension: a cue that starts before the word is spoken is a different defect from a cue with the wrong words in it.
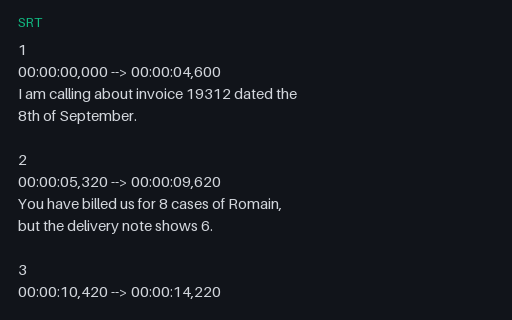
- srtInvoice dispute: timed captionsThe recogniser's output with timings, 4 cues over the full take. Carries the same normalisation as the plain transcript in this group, so it inherits the same scoring trap, and adds the timing dimension: a cue that starts before the word is spoken is a different defect from a cue with the wrong words in it.
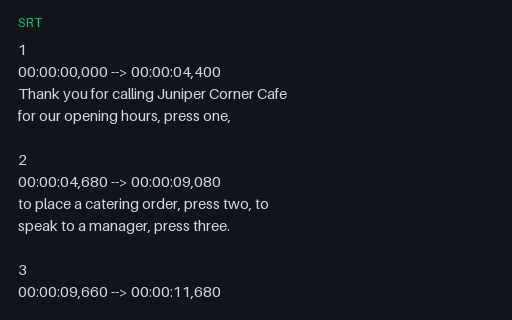
- srtIvr menu: timed captionsThe recogniser's output with timings, 3 cues over the full take. Carries the same normalisation as the plain transcript in this group, so it inherits the same scoring trap, and adds the timing dimension: a cue that starts before the word is spoken is a different defect from a cue with the wrong words in it.
Generated by generation/audio_ladder_wave.py. Free for any use, no attribution required, license.