Harbour Kitchen Group: T4 shaped slip register
T4 shaped slip register for Harbour Kitchen Group. All 8 slips for the period. Box 14 sums to 9,190.00 CAD, which is the base pay the restaurant model records across every rostered shift, and boxes 16, 18 and 22 sum to 546.82, 152.56 and 1,378.50. Every row net_pay_cad is box 14 less those three, and the eight net figures sum to 7,112.12 CAD.
csv
text/csv
- Document Set
- tax
- Industry
- retail
- Source Kit
- retail-commerce
- Entity
- Harbour Kitchen Group
- Synthetic
- true
- As Of
- 2026-09-08
Binary csv: no in-browser preview. Download it above to open in a compatible application.
Specifications
- Document Set
- tax
- Industry
- retail
- Source Kit
- retail-commerce
- Entity
- Harbour Kitchen Group
- Synthetic
- true
- As Of
- 2026-09-08
- Rows
- 8
- Box14 Total
- 9190.00
- Cpp Total
- 546.82
- Ei Total
- 152.56
- Tax Total
- 1378.50
- Net Total
- 7112.12
Testing contract
Expected to pass- Scenario
- Check the net-pay identity on every row, then sum box 14 and compare with the restaurant staffing ledger.
- Expected result
- All 8 rows satisfy net equals box 14 less boxes 16, 18 and 22, and box 14 sums to 9190.00, exactly the base pay total of the staffing shifts in the restaurant model. Rounding each employee separately and adding gives the same totals as the summary, which is stated on the summary itself.
What is a .csv file?
CSV (Comma-Separated Values) is a plain-text tabular format where rows are lines and fields are separated by commas, with quoting rules for values that contain delimiters, quotes, or newlines. It has no formal type system and depends on encoding and dialect conventions. It is the most portable format for tabular data exchange.
How to use this file
Use an example CSV to test parsers against quoting and embedded-delimiter edge cases, header handling, encoding detection, and import pipelines into databases or spreadsheets.
How to use this file for testing
“Harbour Kitchen Group: T4 shaped slip register” is a deterministic Novus Examples fixture for Data import, CSV parsing. Realistic faker-generated datasets with documented schemas for testing import and ETL flows.
Documented properties for this file: 8 rows. Compare results against paired or grouped companions on this page when present (clean↔damaged, searchable↔scanned, or format twins) so scores stay reproducible across runs.
Download the file once, keep the path stable in CI or local scripts, and treat the spec table as the contract: dimensions, seeds, field lists, and roles are intentional. Corrupt or invalid samples are labelled as such, expect parsers to fail loudly rather than silently accept them.
Data fixtures document their exact quirks (delimiters, encodings, null handling, schema, and row counts) in the spec table. Point your parser or importer at the file and assert it handles the documented edge cases; clean and deliberately-messy siblings make before/after diffs straightforward.
Code examples
import pandas as pd

df = pd.read_csv("t4-slips.csv")
print(df.head())
print(df.dtypes)
Related files
- csvFieldnote Supply Shop: Sales tax filing worksheetSales tax filing worksheet for Fieldnote Supply Shop. The 6 jurisdictions this shop collected in during 2026-08-01 to 2026-08-31, taken to the point of remittance. Net tax due sums to 88.88 USD, exactly the figure the wave-one tax-summary.csv reaches by a different route; two jurisdictions allow a vendor collection discount, which takes 0.13 off, so 88.75 USD is actually remitted. 2 rows have an empty permit_number because the two Canadian jurisdictions are filed on the GST/HST return instead.
- csvFieldnote Supply Shop: Sales tax nexus summarySales tax nexus summary for Fieldnote Supply Shop. Why the shop is registered in each of the 6 jurisdictions, with the permit, the filing frequency and the next due date. Due dates range from 2026-09-20 to 2026-10-31, so a reader that assumes one filing calendar across a multi-state seller gets four of the six wrong.
- csvFieldnote Supply Shop: Sales tax payable control accountSales tax payable control account for Fieldnote Supply Shop. The ledger account behind the filing: opening 0.00, credited 96.34 of tax collected, debited 7.46 of tax refunded, leaving 88.88 USD payable at the end of the period. The 0.13 vendor allowance and the 88.75 remittance then clear it to exactly 0.00 on 2026-09-20. The balance after row 3 is the same number the filing worksheet reaches by summing six jurisdictions.
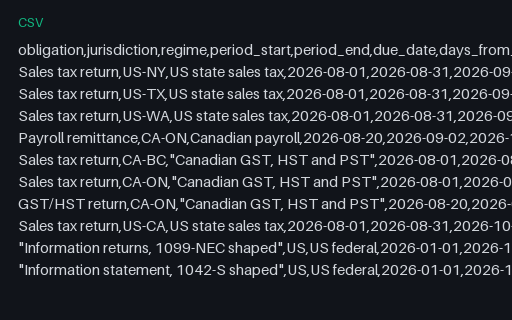
- csvFieldnote Supply Shop: Tax obligation calendarTax obligation calendar for Fieldnote Supply Shop. 10 dated obligations across four regimes and two currencies, in due date order, each with the days from the fixed snapshot and the amount due. The amount column mixes USD and CAD, so it must not be summed without the currency column: doing so gives a meaningless 10399.60.
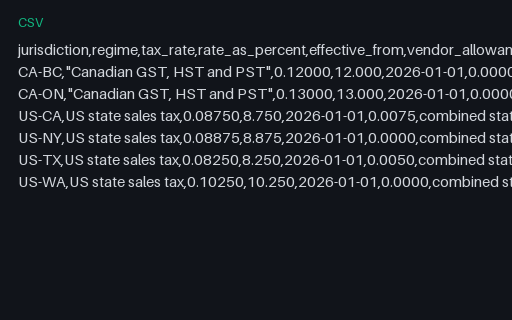
- csvFieldnote Supply Shop: Tax rate tableTax rate table for Fieldnote Supply Shop. The 6 rates as both a decimal and a percentage, so a reader can check one against the other. US-NY at 0.08875 is the one that a float round trip most often damages, and it is carried here to five decimal places and as 8.875 percent.
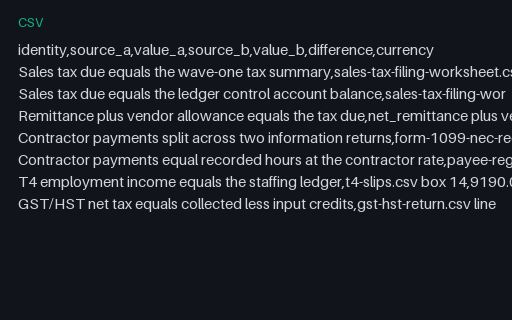
- csvFieldnote Supply Shop: Tax reconciliation, source against sourceTax reconciliation, source against source for Fieldnote Supply Shop. 7 identities stated as a pair of sources and their values, with the difference computed rather than asserted. Every difference is 0.00, and two of the rows reach across into the wave-one ecommerce set and into the crm-services model, so the file is also a cross-set consistency check.
Generated by generation/industry_documents_two.py. Free for any use, no attribution required, license.