Tern Client Services: Specialist utilisation report
Specialist utilisation report for Tern Client Services. 3 specialists against a stated 64 available hours each. Billable hours are 16, 24, 32, so utilisation runs 25.00 to 50.00 percent. Each specialist worked on exactly one project in this period, which is why the projects column is 1 on every row.
csv
text/csv
- Document Set
- professional-services
- Industry
- professional-services
- Source Kit
- crm-services
- Synthetic
- true
- As Of
- 2026-09-08
- Rows
- 3
Binary csv: no in-browser preview. Download it above to open in a compatible application.
Specifications
- Document Set
- professional-services
- Industry
- professional-services
- Source Kit
- crm-services
- Synthetic
- true
- As Of
- 2026-09-08
- Rows
- 3
- Available Hours Each
- 64
- Billable Hours
- 72
- Encoding
- UTF-8
Testing contract
Expected to pass- Scenario
- Group the timesheet export by worker and recompute the utilisation.
- Expected result
- The 3 workers in timesheet-export.csv reproduce these rows exactly: hours sum to 72, billable_value to 7200.00, and every utilisation_percent equals billable_hours times 100 divided by 64 rounded half up to two decimals.
What is a .csv file?
CSV (Comma-Separated Values) is a plain-text tabular format where rows are lines and fields are separated by commas, with quoting rules for values that contain delimiters, quotes, or newlines. It has no formal type system and depends on encoding and dialect conventions. It is the most portable format for tabular data exchange.
How to use this file
Use an example CSV to test parsers against quoting and embedded-delimiter edge cases, header handling, encoding detection, and import pipelines into databases or spreadsheets.
How to use this file for testing
“Tern Client Services: Specialist utilisation report” is a deterministic Novus Examples fixture for Data import. Realistic faker-generated datasets with documented schemas for testing import and ETL flows.
Documented properties for this file: 3 rows · UTF-8. Compare results against paired or grouped companions on this page when present (clean↔damaged, searchable↔scanned, or format twins) so scores stay reproducible across runs.
Download the file once, keep the path stable in CI or local scripts, and treat the spec table as the contract: dimensions, seeds, field lists, and roles are intentional. Corrupt or invalid samples are labelled as such, expect parsers to fail loudly rather than silently accept them.
Data fixtures document their exact quirks (delimiters, encodings, null handling, schema, and row counts) in the spec table. Point your parser or importer at the file and assert it handles the documented edge cases; clean and deliberately-messy siblings make before/after diffs straightforward.
Code examples
import pandas as pd

df = pd.read_csv("utilisation-report.csv")
print(df.head())
print(df.dtypes)
Related files
- csvTern Client Services: Contact export in the semicolon dialectContact export in the semicolon dialect for Tern Client Services. The same 8 contacts written with a semicolon delimiter. The billing_address field is still quoted because it contains newlines, but the tags field is now bare: "billing,renewals" needs no quotes when the delimiter is a semicolon, so the same value is quoted in contacts-export.csv and unquoted here. The file has 33 physical lines.
- csvTern Client Services: Contact export with quoted fieldsContact export with quoted fields for Tern Client Services. 8 contacts in 33 physical lines, because every billing_address is a four-line address held in one quoted field. The addresses also contain commas, the notes contain doubled double-quote characters where a quotation appears, and the tags field holds the comma-separated value "billing,renewals" inside quotes. Every one of those is correctly escaped RFC 4180.
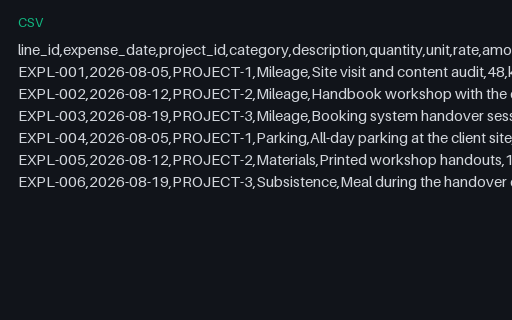
- csvTern Client Services: Expense claim whose mileage was paid at a superseded rateExpense claim whose mileage was paid at a superseded rate for Tern Client Services. The same 6 lines as expense-claim.csv, but the three mileage amounts were computed at the superseded 0.58 per kilometre while the rate column still reads 0.62. The mileage subtotal is 136.88 where 236 km at the stated rate is 146.32, so the claim is 9.44 light and totals 212.13 instead of 221.57.
- csvTern Client Services: Expense claim with mileageExpense claim with mileage for Tern Client Services. 6 claim lines for August: 3 mileage lines worth 146.32 and 3 receipted lines worth 75.25, 221.57 in total. amount equals quantity times rate on every line, including the mileage lines where quantity is kilometres. Each line carries the project it belongs to and a receipt reference.
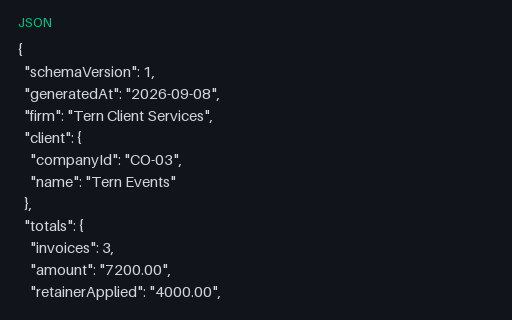
- jsonTern Client Services: Invoice register JSONInvoice register JSON for Tern Client Services. The same 3 invoices as invoice-register.csv with the settlement rule stated: the retainer is drawn while a balance remains and the remainder is billed. totals.outstanding is 3200.00.
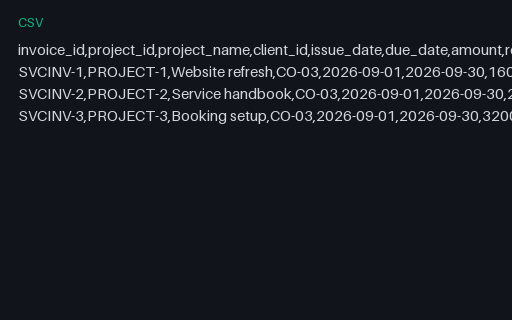
- csvTern Client Services: Invoice register with retainer drawsInvoice register with retainer draws for Tern Client Services. 3 invoices totalling 7200.00, which is the whole of the August timesheet. 4000.00 of it was settled by drawing the retainer to nil and 3200.00 is outstanding on SVCINV-3. amount equals retainer_applied plus cash_due on every row, and every invoice is dated 2026-09-30, 22 days after the 2026-09-08 snapshot, so all three sit in the not yet due bucket.
Generated by generation/industry_documents.py. Free for any use, no attribution required, license.