Pine Assembly Workshop: Work order cost build-up
Work order cost build-up for Pine Assembly Workshop. The seven line cost of BUILD-1: 50.40 USD of material, 18.50 of labour and 11.10 of absorbed overhead, giving 80.00 USD against a standard cost of 80.00 USD for the output and a variance of 0.00. The order closes exactly to standard, which is deliberate: it makes any variance a reader computes a defect in their arithmetic rather than a property of the fixture.
csv
text/csv
- Document Set
- manufacturing
- Industry
- manufacturing
- Source Kit
- inventory-manufacturing
- Entity
- Pine Assembly Workshop
- Synthetic
- true
- As Of
- 2026-09-08
Binary csv: no in-browser preview. Download it above to open in a compatible application.
Specifications
- Document Set
- manufacturing
- Industry
- manufacturing
- Source Kit
- inventory-manufacturing
- Entity
- Pine Assembly Workshop
- Synthetic
- true
- As Of
- 2026-09-08
- Rows
- 7
- Material
- 50.40
- Labour
- 18.50
- Overhead
- 11.10
- Order Cost
- 80.00
- Standard Cost
- 80.00
- Variance
- 0.00
Testing contract
Expected to pass- Scenario
- Recompute each line from the basis it names and check the variance.
- Expected result
- Line 1 is 2 times 25.20, which is 50.40; line 2 is 30 minutes at 37.00, which is 18.50; line 3 is 60 percent of that, 11.10; and line 5 is 80.00, exactly the 80.00 standard cost of 2 finished units, so line 7 is 0.00.
What is a .csv file?
CSV (Comma-Separated Values) is a plain-text tabular format where rows are lines and fields are separated by commas, with quoting rules for values that contain delimiters, quotes, or newlines. It has no formal type system and depends on encoding and dialect conventions. It is the most portable format for tabular data exchange.
How to use this file
Use an example CSV to test parsers against quoting and embedded-delimiter edge cases, header handling, encoding detection, and import pipelines into databases or spreadsheets.
How to use this file for testing
“Pine Assembly Workshop: Work order cost build-up” is a deterministic Novus Examples fixture for Data import, CSV parsing. Realistic faker-generated datasets with documented schemas for testing import and ETL flows.
Documented properties for this file: 7 rows. Compare results against paired or grouped companions on this page when present (clean↔damaged, searchable↔scanned, or format twins) so scores stay reproducible across runs.
Download the file once, keep the path stable in CI or local scripts, and treat the spec table as the contract: dimensions, seeds, field lists, and roles are intentional. Corrupt or invalid samples are labelled as such, expect parsers to fail loudly rather than silently accept them.
Data fixtures document their exact quirks (delimiters, encodings, null handling, schema, and row counts) in the spec table. Point your parser or importer at the file and assert it handles the documented edge cases; clean and deliberately-messy siblings make before/after diffs straightforward.
Code examples
import pandas as pd

df = pd.read_csv("work-order-cost.csv")
print(df.head())
print(df.dtypes)
Related files
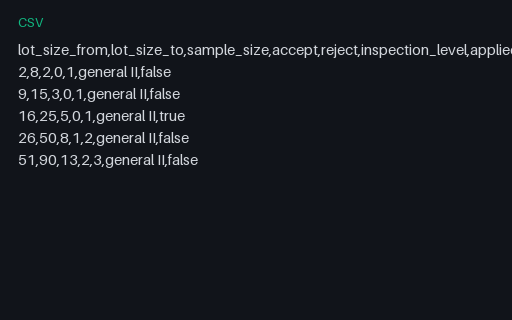
- csvPine Assembly Workshop: Attribute sampling planAttribute sampling plan for Pine Assembly Workshop. The sampling table the inspection used. The lot of 16 legs, being the quantity issued to BUILD-1 and BUILD-2 together, falls in the 16 to 25 band, which calls for a sample of 5 and an accept number of 0, and 5 is exactly the number of samples inspection-measurements.csv holds for each characteristic. With an accept number of 0 and 2 nonconforming readings, the lot is rejected on the plan and dealt with by nonconformance rather than by acceptance.
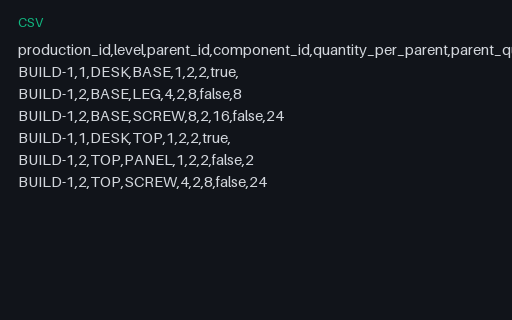
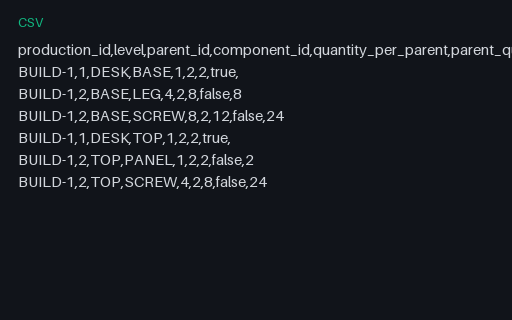
- csvPine Assembly Workshop: Bill of materials exploded for a production orderBill of materials exploded for a production order for Pine Assembly Workshop. The same structure exploded for BUILD-1, an order for 2 DESK. Extended quantity is quantity per parent times parent quantity on every row, and the leaf totals of 8 LEG, 2 PANEL and 24 SCREW equal the material requirements the inventory-manufacturing model already holds for that order, which the model_requirement column repeats on each leaf row for comparison.
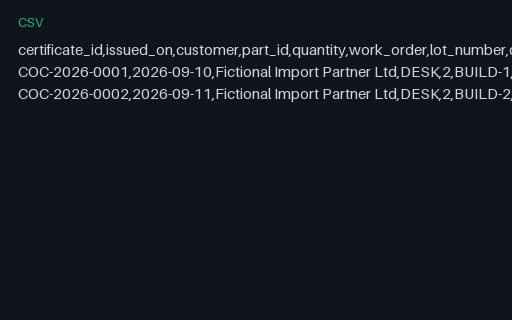
- csvPine Assembly Workshop: Certificate of conformance registerCertificate of conformance register for Pine Assembly Workshop. Two certificates against the same lot and the same inspection report, one per production order. The first discloses 2 nonconformances and the second none, because the nonconforming legs were consumed by the replacement on the first order and the second order drew clean stock from the same lot.
- csvPine Assembly Workshop: Exploded bill of materials whose sub-assembly quantities do not roll upExploded bill of materials whose sub-assembly quantities do not roll up for Pine Assembly Workshop. The same 6 rows with one number changed: the SCREW line under BASE carries an extended quantity of 12 instead of 16. That row now says 8 per parent times 2 parents is 12, which is arithmetically false, and the SCREW leaf total falls to 20 against the 24 the model_requirement_component_total column on the same rows still declares. The shortfall is 4 screws, 0.40 USD of material, and it is enough to leave one BASE sub-assembly short at build time.
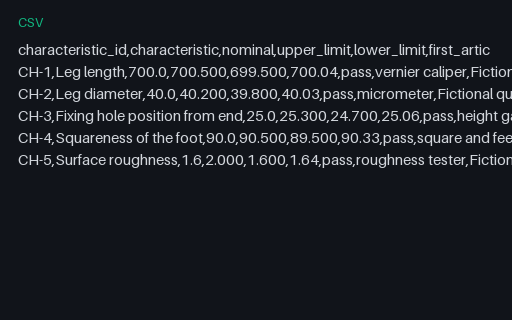
- csvPine Assembly Workshop: First article inspectionFirst article inspection for Pine Assembly Workshop. The first article record for LEG against DRW-LEG-002 revision C: all 5 characteristics measured and passed before the run started. The readings are the fourth sample from the production inspection, which is deliberate: the first article passes on every characteristic while the production lot later fails on two, so the pair shows that a clean first article does not guarantee a clean run.
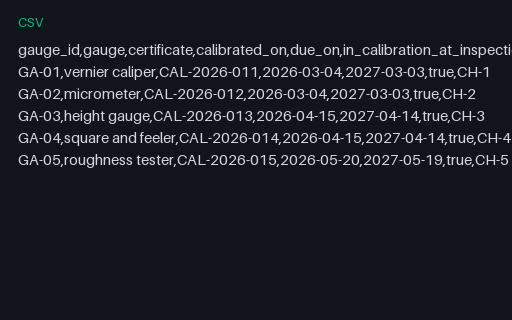
- csvPine Assembly Workshop: Gauge calibration registerGauge calibration register for Pine Assembly Workshop. The 5 gauges used on this inspection, each with its calibration certificate, the date it was calibrated and the date it falls due. All 5 were inside calibration on 2026-09-10, the inspection date, and the used_for column names the characteristics each one measured, so every characteristic can be traced to a gauge and every gauge to a certificate.
Generated by generation/industry_documents_two.py. Free for any use, no attribution required, license.