Fieldnote Supply Shop: Sales by product
Sales by product for Fieldnote Supply Shop. 6 products with units sold, gross merchandise before discount, units refunded and net merchandise. gross_merchandise sums to 942.00, which is the merchandise subtotal of orders-export.csv before the four 5.00 promotions, and merchandise_refunded sums to 80.00.
csv
text/csv
- Document Set
- ecommerce
- Industry
- retail
- Source Kit
- retail-commerce
- Synthetic
- true
- As Of
- 2026-09-08
- Rows
- 6
Binary csv: no in-browser preview. Download it above to open in a compatible application.
Specifications
- Document Set
- ecommerce
- Industry
- retail
- Source Kit
- retail-commerce
- Synthetic
- true
- As Of
- 2026-09-08
- Rows
- 6
- Encoding
- UTF-8
Testing contract
Expected to pass- Scenario
- Group order-lines-export.csv and refunds.csv by product and compare with this report.
- Expected result
- The 6 rows reproduce from the line export exactly; net_merchandise equals gross_merchandise minus merchandise_refunded on every row and the column sums to 862.00.
What is a .csv file?
CSV (Comma-Separated Values) is a plain-text tabular format where rows are lines and fields are separated by commas, with quoting rules for values that contain delimiters, quotes, or newlines. It has no formal type system and depends on encoding and dialect conventions. It is the most portable format for tabular data exchange.
How to use this file
Use an example CSV to test parsers against quoting and embedded-delimiter edge cases, header handling, encoding detection, and import pipelines into databases or spreadsheets.
How to use this file for testing
“Fieldnote Supply Shop: Sales by product” is a deterministic Novus Examples fixture for Data import. Realistic faker-generated datasets with documented schemas for testing import and ETL flows.
Documented properties for this file: 6 rows · UTF-8. Compare results against paired or grouped companions on this page when present (clean↔damaged, searchable↔scanned, or format twins) so scores stay reproducible across runs.
Download the file once, keep the path stable in CI or local scripts, and treat the spec table as the contract: dimensions, seeds, field lists, and roles are intentional. Corrupt or invalid samples are labelled as such, expect parsers to fail loudly rather than silently accept them.
Data fixtures document their exact quirks (delimiters, encodings, null handling, schema, and row counts) in the spec table. Point your parser or importer at the file and assert it handles the documented edge cases; clean and deliberately-messy siblings make before/after diffs straightforward.
Code examples
import pandas as pd

df = pd.read_csv("sales-by-product.csv")
print(df.head())
print(df.dtypes)
Related files
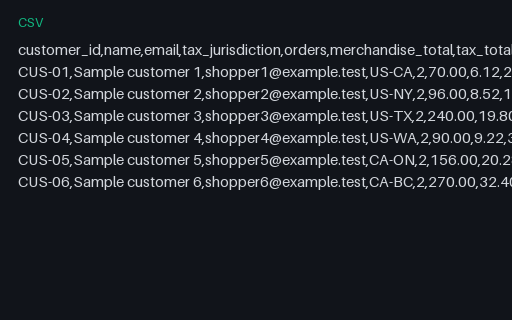
- csvFieldnote Supply Shop: Customer export with tax jurisdictionCustomer export with tax jurisdiction for Fieldnote Supply Shop. 6 fictional customers at example.test addresses, each with the jurisdiction that set the tax rate on their orders. Every customer placed 2 orders and merchandise_total sums to 922.00.
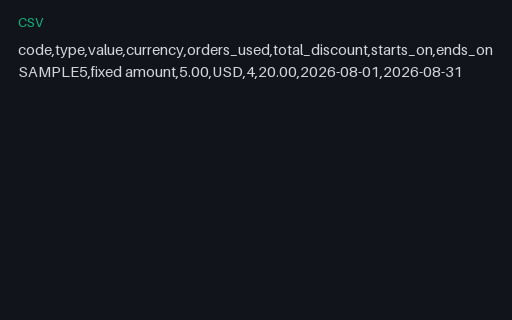
- csvFieldnote Supply Shop: Discount code usageDiscount code usage for Fieldnote Supply Shop. One promotion, SAMPLE5, a fixed 5.00 USD reduction used on 4 of the 12 orders for a total of 20.00. Those are exactly the orders whose discount_total column in orders-export.csv is not zero.
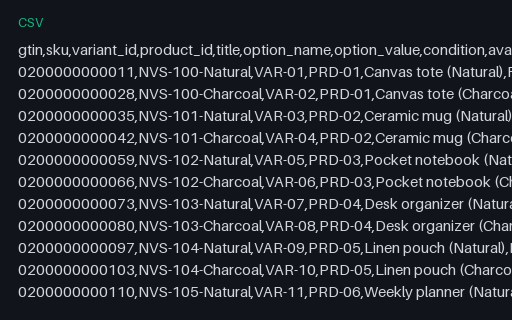
- csvFieldnote Supply Shop: Inventory and price feed with variantsInventory and price feed with variants for Fieldnote Supply Shop. 12 variant rows over 6 products, two finishes each. Every gtin is a valid 13-digit GS1 number whose final digit is the modulo-10 check digit, and all 12 begin with a zero, so a spreadsheet that types the column as a number destroys the identifier. Quantities sum to 285 units and match the variant stock in the shop model.
- xmlFieldnote Supply Shop: Inventory and price feed XMLInventory and price feed XML for Fieldnote Supply Shop. The same 12 variants as inventory-feed.csv. Because the gtin values are element text rather than spreadsheet cells, the leading zeros survive here, which makes this file the reference against which the CSV round trip is checked.
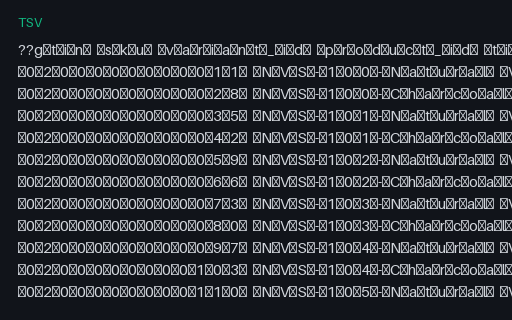
- tsvFieldnote Supply Shop: Inventory feed as UTF-16 LE tab-separated textInventory feed as UTF-16 LE tab-separated text for Fieldnote Supply Shop. The same 12 variants, tab separated and encoded UTF-16 little endian with an FF FE byte order mark. Every ASCII character occupies two bytes, so a reader that opens the file as UTF-8 sees NUL between each letter and usually reports one column.
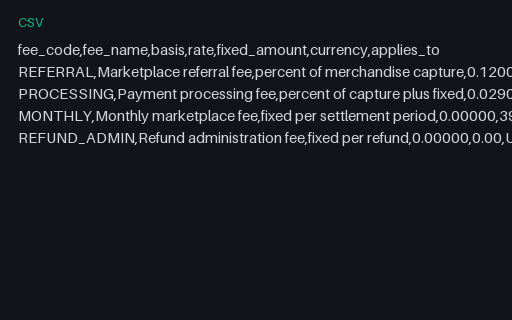
- csvFieldnote Supply Shop: Marketplace fee scheduleMarketplace fee schedule for Fieldnote Supply Shop. The four fee codes the settlement uses, with basis, rate and fixed component. REFERRAL at 0.12000 and PROCESSING at 0.02900 plus 0.30 reproduce every fee line in settlement-transactions.csv; REFUND_ADMIN is present at zero because the period waived it, which is why the settlement has no refund fee lines.
Generated by generation/industry_documents.py. Free for any use, no attribution required, license.