Alder Table Bistro: Drinks list as data
Drinks list as data for Alder Table Bistro. 8 rows and 7 columns pairing every printed drink line with the till item code it imports as, the serve size in millilitres and the basis of its price. The three drinks sold both ways appear twice, once per service.
csv
text/csv
- Kit
- restaurant-bistro
- Industry
- food-service
- Schema Version
- 1
- Synthetic
- true
- As Of
- 2026-09-08
- Currency
- CAD
Binary csv: no in-browser preview. Download it above to open in a compatible application.
Specifications
- Kit
- restaurant-bistro
- Industry
- food-service
- Schema Version
- 1
- Synthetic
- true
- As Of
- 2026-09-08
- Currency
- CAD
- Menu Items
- 4
- Rows
- 8
- Columns
- 7
- Delimiter
- ,
- Encoding
- UTF-8
- Line Endings
- LF
Testing contract
Expected to pass- Scenario
- Use drinks list as data in the Alder Table Bistro menu, allergen and till import workflow.
- Expected result
- 8 rows and 7 columns pairing every printed drink line with the till item code it imports as, the serve size in millilitres and the basis of its price. The three drinks sold both ways appear twice, once per service.
What is a .csv file?
CSV (Comma-Separated Values) is a plain-text tabular format where rows are lines and fields are separated by commas, with quoting rules for values that contain delimiters, quotes, or newlines. It has no formal type system and depends on encoding and dialect conventions. It is the most portable format for tabular data exchange.
How to use this file
Use an example CSV to test parsers against quoting and embedded-delimiter edge cases, header handling, encoding detection, and import pipelines into databases or spreadsheets.
How to use this file for testing
“Alder Table Bistro: Drinks list as data” is a deterministic Novus Examples fixture for Data import, CSV parsing. Realistic faker-generated datasets with documented schemas for testing import and ETL flows.
Documented properties for this file: 8 rows · 7 columns · UTF-8 · LF. Compare results against paired or grouped companions on this page when present (clean↔damaged, searchable↔scanned, or format twins) so scores stay reproducible across runs.
Download the file once, keep the path stable in CI or local scripts, and treat the spec table as the contract: dimensions, seeds, field lists, and roles are intentional. Corrupt or invalid samples are labelled as such, expect parsers to fail loudly rather than silently accept them.
Data fixtures document their exact quirks (delimiters, encodings, null handling, schema, and row counts) in the spec table. Point your parser or importer at the file and assert it handles the documented edge cases; clean and deliberately-messy siblings make before/after diffs straightforward.
Code examples
import pandas as pd

df = pd.read_csv("drinks-list.csv")
print(df.head())
print(df.dtypes)
Related files
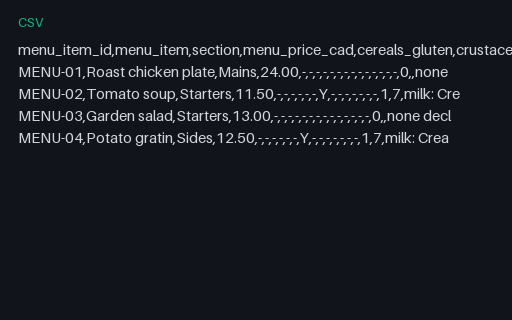
- csvAlder Table Bistro: Allergen menu as dataAllergen menu as data for Alder Table Bistro. 4 rows and 21 columns: the menu item id, the printed section, the menu price, the 14 allergen columns, the declared count and the ingredient sources. 2 of 4 dishes declare at least one allergen. Joins to printed-menu.pdf and to plate-costs.csv on menu_item_id.
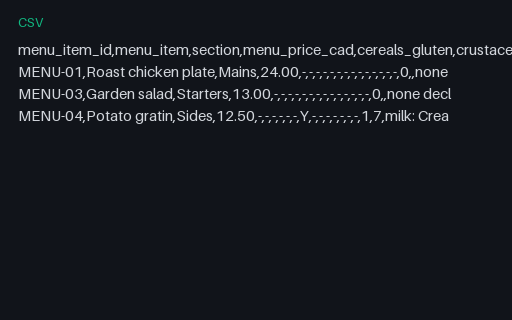
- csvAlder Table Bistro: Allergen menu missing a dish on the menuAllergen menu missing a dish on the menu for Alder Table Bistro. Intentionally incomplete. 3 rows where allergen-menu.csv has 4. MENU-02 Tomato soup is printed on printed-menu.pdf at 11.50 CAD and declares 1 allergen in the costing folder, and it has no row here. The remaining rows are correct.
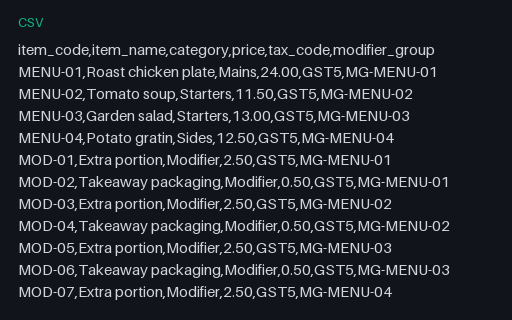
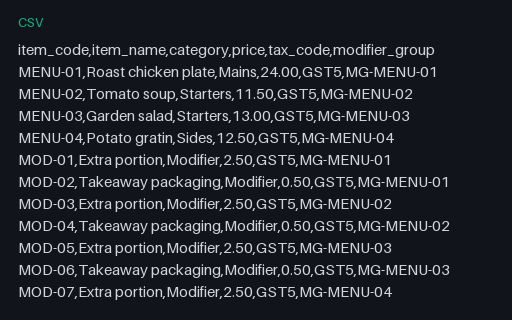
- csvAlder Table Bistro: Till importTill import for Alder Table Bistro. 21 rows and 6 columns in the shape a point of sale ingests: item_code, item_name, category, price, tax_code, modifier_group. 4 dishes, 8 modifier options across 4 groups, 8 drink lines and one stored value line. Item codes are letter prefixed so a spreadsheet cannot eat a leading zero, and two tax codes are present so a mapping has something to map.
- csvAlder Table Bistro: Till import in the European dialectTill import in the European dialect for Alder Table Bistro. The same 21 rows as pos-import.csv in the other dialect a till exports: semicolon delimited, decimal comma in the price column, Latin-1 encoded and CRLF terminated. It carries the non-ASCII characters "é", so reading it as UTF-8 raises a decode error instead of silently producing mojibake.
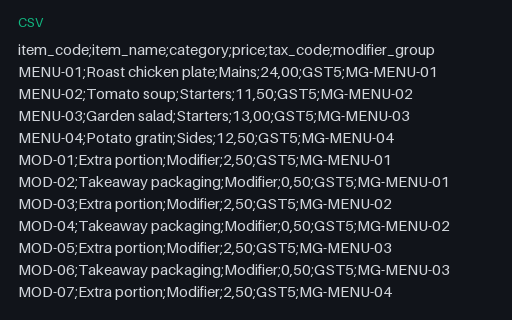
- csvAlder Table Bistro: Till import with a duplicate item codeTill import with a duplicate item code for Alder Table Bistro. Intentionally invalid. 22 rows where pos-import.csv has 21. item_code MENU-02 appears on line 3 at 11.50 CAD and again on line 23 at 12.50 CAD, which is the proposed price in the shared menu_price_changes table. It is the only repeated code in the file, so an importer that keeps the last row it reads silently ships the later price.
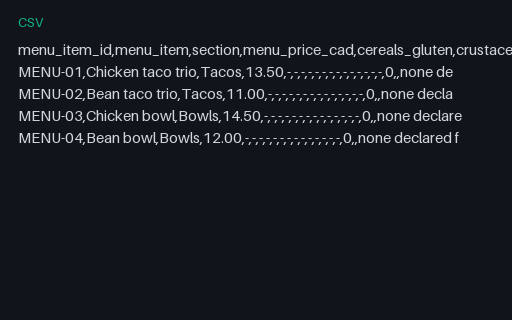
- csvCedar Street Tacos: Allergen menu as dataAllergen menu as data for Cedar Street Tacos. 4 rows and 21 columns: the menu item id, the printed section, the menu price, the 14 allergen columns, the declared count and the ingredient sources. 0 of 4 dishes declare at least one allergen. Joins to printed-menu.pdf and to plate-costs.csv on menu_item_id.
Generated by generation/restaurant_menus.py. Free for any use, no attribution required, license.