Cobalt Operations Team: Employee directory
Employee directory for Cobalt Operations Team. 8 employees with department, pay basis, rate and start date. The names are the model's own role labels, not people, and the directory carries no address, telephone number, date of birth or national identifier. The bank fields are reserved test values: sort code 000000 and sequential account numbers from 00000001 to 00000008, flagged as such in the last column.
csv
text/csv
- Document Set
- payroll
- Industry
- people-operations
- Source Kit
- people-operations
- Synthetic
- true
- As Of
- 2026-09-08
- Rows
- 8
Binary csv: no in-browser preview. Download it above to open in a compatible application.
Specifications
- Document Set
- payroll
- Industry
- people-operations
- Source Kit
- people-operations
- Synthetic
- true
- As Of
- 2026-09-08
- Rows
- 8
- Sensitive Fields
- 0
- Synthetic Bank Details
- true
- Encoding
- UTF-8
Testing contract
Expected to pass- Scenario
- Import the directory and check both the rates and what personal data it contains.
- Expected result
- All 8 hourly_rate values equal the hourly_rate column of payroll-register.csv, and every row carries identifiers_are_test_values true with a sort code of 000000. No column holds an address, telephone number, date of birth or national identifier, so the file is a safe shape to test an HR import against.
What is a .csv file?
CSV (Comma-Separated Values) is a plain-text tabular format where rows are lines and fields are separated by commas, with quoting rules for values that contain delimiters, quotes, or newlines. It has no formal type system and depends on encoding and dialect conventions. It is the most portable format for tabular data exchange.
How to use this file
Use an example CSV to test parsers against quoting and embedded-delimiter edge cases, header handling, encoding detection, and import pipelines into databases or spreadsheets.
How to use this file for testing
“Cobalt Operations Team: Employee directory” is a deterministic Novus Examples fixture for Data import. Realistic faker-generated datasets with documented schemas for testing import and ETL flows.
Documented properties for this file: 8 rows · UTF-8. Compare results against paired or grouped companions on this page when present (clean↔damaged, searchable↔scanned, or format twins) so scores stay reproducible across runs.
Download the file once, keep the path stable in CI or local scripts, and treat the spec table as the contract: dimensions, seeds, field lists, and roles are intentional. Corrupt or invalid samples are labelled as such, expect parsers to fail loudly rather than silently accept them.
Data fixtures document their exact quirks (delimiters, encodings, null handling, schema, and row counts) in the spec table. Point your parser or importer at the file and assert it handles the documented edge cases; clean and deliberately-messy siblings make before/after diffs straightforward.
Code examples
import pandas as pd

df = pd.read_csv("employee-directory.csv")
print(df.head())
print(df.dtypes)
Related files
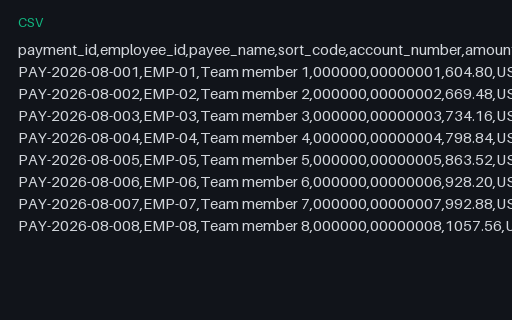
- csvCobalt Operations Team: Bank payment fileBank payment file for Cobalt Operations Team. 8 payments, one per employee, for the net pay on payroll-register.csv. The amount column totals 6649.44, which is the net_pay total of the register to the cent. Sort code and account numbers are reserved test values and the reference on every line names the employee and the period.
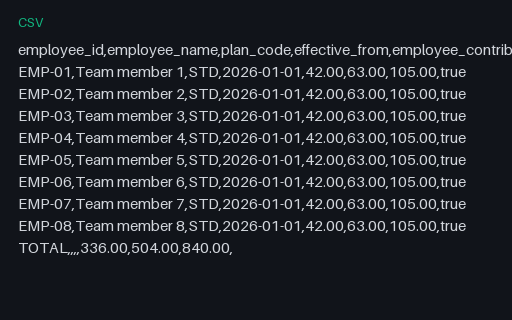
- csvCobalt Operations Team: Benefit deduction scheduleBenefit deduction schedule for Cobalt Operations Team. 8 employees and a TOTAL row. Every employee is on the STD plan from 2026-01-01, contributing 42.00 against an employer contribution of 63.00, so employee contributions total 336.00, employer contributions 504.00 and premiums 840.00. Only the employee side reaches the payroll register; the employer side is a cost, not a deduction.
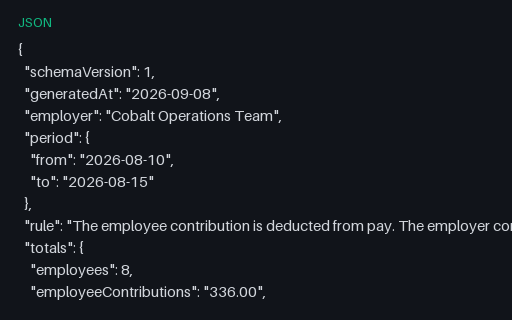
- jsonCobalt Operations Team: Benefit deduction schedule JSONBenefit deduction schedule JSON for Cobalt Operations Team. The same 8 enrolments as benefits-deduction-schedule.csv with the rule that separates a deduction from an employer cost stated in words. totalPremiums is 840.00, of which only 336.00 is deducted from pay.
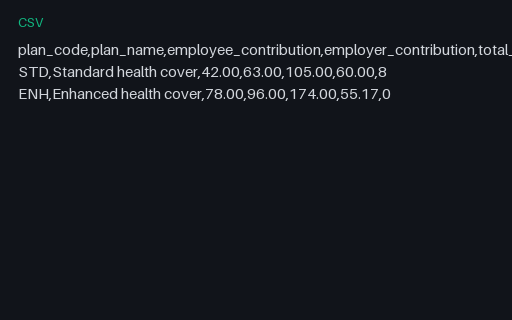
- csvCobalt Operations Team: Benefit plan rate cardBenefit plan rate card for Cobalt Operations Team. Two health plans. STD costs 105.00 a period of which the employer pays 63.00, 60.00 percent, and all 8 employees are on it. ENH is defined at 174.00 with nobody enrolled, so it is the negative case: a plan that exists in the rate card and must never appear in a deduction.
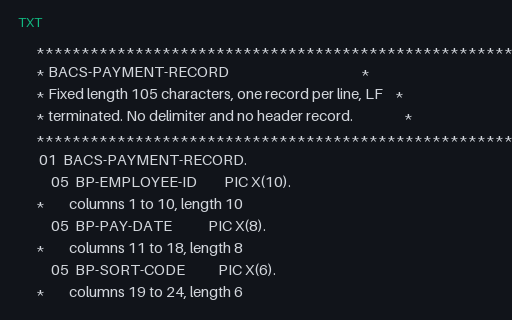
- txtCobalt Operations Team: COBOL copybook for the payment fileCOBOL copybook for the payment file for Cobalt Operations Team. A COBOL record description for the same 105-character layout, with PIC clauses matching bank-payment-layout.json field for field: X(n) for the alphanumeric fields and 9(9)V99 for the amount, which is where the two implied decimal places are declared. Comment lines carry the column ranges.
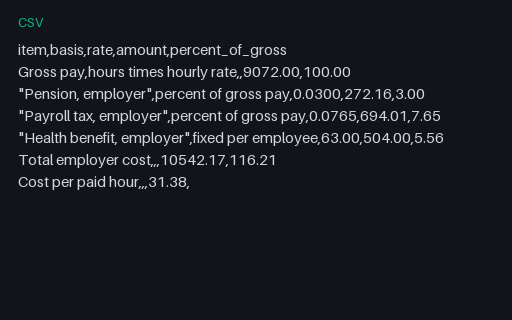
- csvCobalt Operations Team: Employer cost summaryEmployer cost summary for Cobalt Operations Team. What the period actually costs the employer: 9072.00 of gross pay plus 272.16 of employer pension, 694.01 of payroll tax and 504.00 of health contribution, 10542.17 in total, which is 116.21 percent of gross and 31.38 per paid hour. None of it is deducted from pay: employees receive 6649.44.
Generated by generation/industry_documents.py. Free for any use, no attribution required, license.