Pine Property Services: Schedule of insured vehicles
Schedule of insured vehicles for Pine Property Services. The 4 scheduled vehicles with the delivery route each is assigned to and a flat 620.00 USD premium each, which is the 2,480.00 USD commercial auto line on the policy schedule. The vehicle and route identifiers are the ones the inventory-manufacturing model holds.
csv
text/csv
- Document Set
- insurance
- Industry
- trades-property
- Source Kit
- trades-property
- Entity
- Pine Property Services
- Synthetic
- true
- As Of
- 2026-09-08
Binary csv: no in-browser preview. Download it above to open in a compatible application.
Specifications
- Document Set
- insurance
- Industry
- trades-property
- Source Kit
- trades-property
- Entity
- Pine Property Services
- Synthetic
- true
- As Of
- 2026-09-08
- Rows
- 4
- Premium Total
- 2480.00
Testing contract
Expected to pass- Scenario
- Multiply the row count by the per-vehicle premium and compare with the commercial auto line of premium-breakdown.csv.
- Expected result
- 4 vehicles at 620.00 is 2480.00, the commercial auto premium, and every route_id resolves against the wave-one logistics route plan.
What is a .csv file?
CSV (Comma-Separated Values) is a plain-text tabular format where rows are lines and fields are separated by commas, with quoting rules for values that contain delimiters, quotes, or newlines. It has no formal type system and depends on encoding and dialect conventions. It is the most portable format for tabular data exchange.
How to use this file
Use an example CSV to test parsers against quoting and embedded-delimiter edge cases, header handling, encoding detection, and import pipelines into databases or spreadsheets.
How to use this file for testing
“Pine Property Services: Schedule of insured vehicles” is a deterministic Novus Examples fixture for Data import, CSV parsing. Realistic faker-generated datasets with documented schemas for testing import and ETL flows.
Documented properties for this file: 4 rows. Compare results against paired or grouped companions on this page when present (clean↔damaged, searchable↔scanned, or format twins) so scores stay reproducible across runs.
Download the file once, keep the path stable in CI or local scripts, and treat the spec table as the contract: dimensions, seeds, field lists, and roles are intentional. Corrupt or invalid samples are labelled as such, expect parsers to fail loudly rather than silently accept them.
Data fixtures document their exact quirks (delimiters, encodings, null handling, schema, and row counts) in the spec table. Point your parser or importer at the file and assert it handles the documented edge cases; clean and deliberately-messy siblings make before/after diffs straightforward.
Code examples
import pandas as pd

df = pd.read_csv("schedule-of-vehicles.csv")
print(df.head())
print(df.dtypes)
Related files
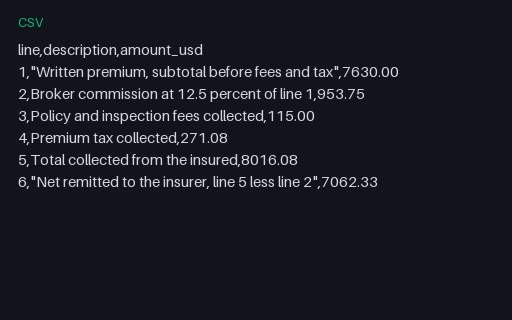
- csvPine Property Services: Broker account statementBroker account statement for Pine Property Services. The broker side of the same premium: 7,630.00 USD of written premium, 12.5 percent commission of 953.75 USD, and 7,062.33 USD remitted to the insurer out of the 8,016.08 USD collected. Commission is charged on the subtotal only, not on the fees or the tax, which is why line 2 is not a percentage of line 5.
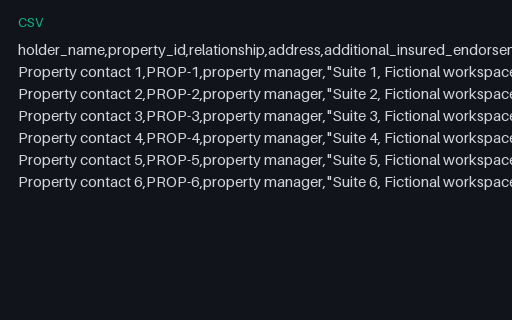
- csvPine Property Services: Certificate holder registerCertificate holder register for Pine Property Services. The 6 parties who require a certificate, each naming the endorsement that makes them an additional insured and the endorsement that waives subrogation. Every holder appears exactly once in certificate-of-insurance-register.csv.
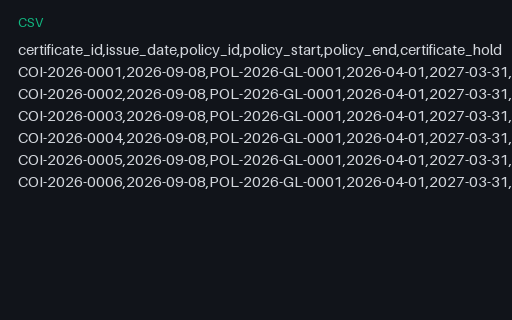
- csvPine Property Services: Certificate of insurance registerCertificate of insurance register for Pine Property Services. 6 certificates, one per scheduled property, all issued 2026-09-08 against policy POL-2026-GL-0001 and all expiring 2027-03-31. days_until_expiry is 204 on every row, which is policy_end minus issue_date, and every row is positive because every certificate was issued while its cover was live.
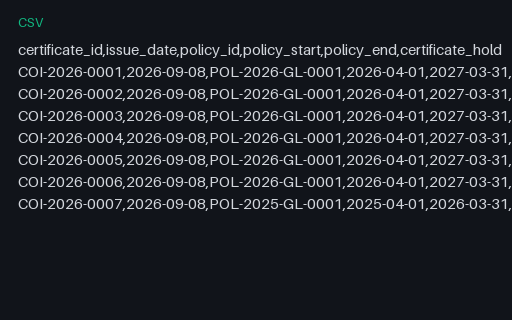
- csvPine Property Services: Certificate register with a certificate that expired before it was issuedCertificate register with a certificate that expired before it was issued for Pine Property Services. The same 6 valid rows with a seventh added: COI-2026-0007 is issued 2026-09-08 against a policy period that ended 2026-03-31, 161 days earlier, and its days_until_expiry cell reads -161. The row is internally consistent, so the arithmetic check passes and only the business rule that a certificate cannot be issued after its cover ends catches it. Its status still says in force.
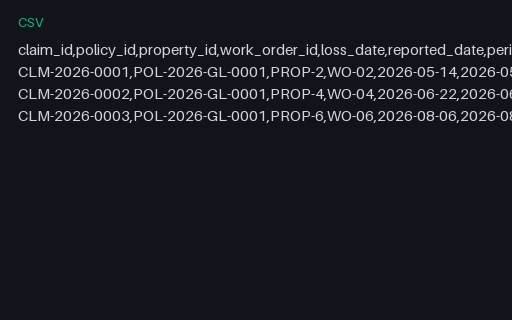
- csvPine Property Services: Claim registerClaim register for Pine Property Services. 3 claims against policy POL-2026-GL-0001, each joined to the work order and property the trades-property model holds. incurred_usd is paid_usd plus reserve_usd on every row; the three rows sum to 17,890.00 paid, 2,760.00 reserved and 20,650.00 incurred. One claim closed without payment because it was assessed below the 1,000.00 USD deductible.
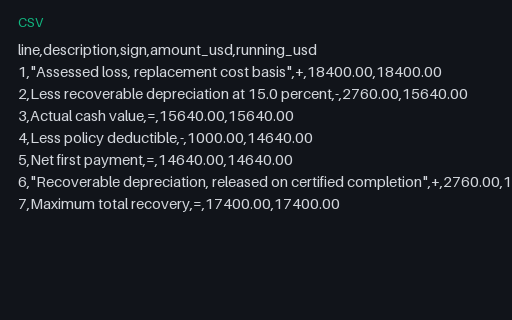
- csvPine Property Services: Claim settlement linesClaim settlement lines for Pine Property Services. The same seven lines as the settlement statement with the sign held in its own column rather than embedded in the amount, so amounts are all positive and a reader has to apply the sign to reproduce the running balance. Applying the signs in order reproduces every running value and ends at 17400.00.
Generated by generation/industry_documents_two.py. Free for any use, no attribution required, license.