Juniper Fitness and Clinic Administration: Provider roster
Provider roster for Juniper Fitness and Clinic Administration. The 3 providers with ten-digit identifiers in the national provider identifier shape. Each one carries a real modulo-10 check digit computed over the 80840 prefix and the nine-digit body, so a validator that implements the check digit rule accepts all of them, and the roster records that it did.
csv
text/csv
- Document Set
- healthcare
- Industry
- fitness-clinic-administration
- Source Kit
- appointment-capacity
- Entity
- Juniper Fitness and Clinic Administration
- Synthetic
- true
- As Of
- 2026-09-08
Binary csv: no in-browser preview. Download it above to open in a compatible application.
Specifications
- Document Set
- healthcare
- Industry
- fitness-clinic-administration
- Source Kit
- appointment-capacity
- Entity
- Juniper Fitness and Clinic Administration
- Synthetic
- true
- As Of
- 2026-09-08
- Rows
- 3
- Check Digit Algorithm
- Luhn over 80840 prefix
- Invalid Identifiers
- 0
Testing contract
Expected to pass- Scenario
- Recompute the check digit on every identifier, including the billing identifier.
- Expected result
- All 3 provider identifiers and the shared billing identifier 1000000012 pass the check digit test, which is why npi_check_digit_valid is true on every row. Changing any single digit makes the test fail.
What is a .csv file?
CSV (Comma-Separated Values) is a plain-text tabular format where rows are lines and fields are separated by commas, with quoting rules for values that contain delimiters, quotes, or newlines. It has no formal type system and depends on encoding and dialect conventions. It is the most portable format for tabular data exchange.
How to use this file
Use an example CSV to test parsers against quoting and embedded-delimiter edge cases, header handling, encoding detection, and import pipelines into databases or spreadsheets.
How to use this file for testing
“Juniper Fitness and Clinic Administration: Provider roster” is a deterministic Novus Examples fixture for Data import, CSV parsing. Realistic faker-generated datasets with documented schemas for testing import and ETL flows.
Documented properties for this file: 3 rows. Compare results against paired or grouped companions on this page when present (clean↔damaged, searchable↔scanned, or format twins) so scores stay reproducible across runs.
Download the file once, keep the path stable in CI or local scripts, and treat the spec table as the contract: dimensions, seeds, field lists, and roles are intentional. Corrupt or invalid samples are labelled as such, expect parsers to fail loudly rather than silently accept them.
Data fixtures document their exact quirks (delimiters, encodings, null handling, schema, and row counts) in the spec table. Point your parser or importer at the file and assert it handles the documented edge cases; clean and deliberately-messy siblings make before/after diffs straightforward.
Code examples
import pandas as pd

df = pd.read_csv("provider-roster.csv")
print(df.head())
print(df.dtypes)
Related files
- csvJuniper Fitness and Clinic Administration: Claim status registerClaim status register for Juniper Fitness and Clinic Administration. All 16 claims with the status code the 835 CLP02 carries, the payer control number and the 17 days between submission and payment. 1 claim is status 4, denied, and the rest are status 1, processed as primary. Every payer control number is unique and appears once in remittance-835.edi.
- csvJuniper Fitness and Clinic Administration: Denial registerDenial register for Juniper Fitness and Clinic Administration. The single denied claim, CLM-0011, denied in full for 85.00 USD under CO 97 with a 90 day appeal deadline of 2026-12-24. The group code is CO, so the amount is a contractual write-off and must not be billed to the patient even though nothing was paid, which is exactly the case a reader gets wrong by assuming an unpaid claim becomes a patient balance.
- csvJuniper Fitness and Clinic Administration: Encounter registerEncounter register for Juniper Fitness and Clinic Administration. 16 encounters, one for each confirmed booking in the appointment model. The two cancelled bookings are absent, so the register has 16 rows where the booking table has 18. Charges sum to 1,180.00 USD across 18 service lines, allowed to 876.00, and the payers paid 700.80 leaving 175.20 with patients.
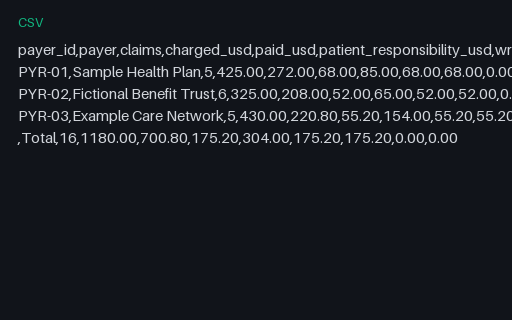
- csvJuniper Fitness and Clinic Administration: Receivable aging by payerReceivable aging by payer for Juniper Fitness and Clinic Administration. The 3 payers plus a total row. On every row paid plus patient responsibility plus written off equals charged, and the three aging buckets sum to the outstanding column. Nothing is older than thirty days because every claim was paid 17 days after submission, so the whole 175.20 USD outstanding sits in the first bucket and is owed by patients rather than by payers.
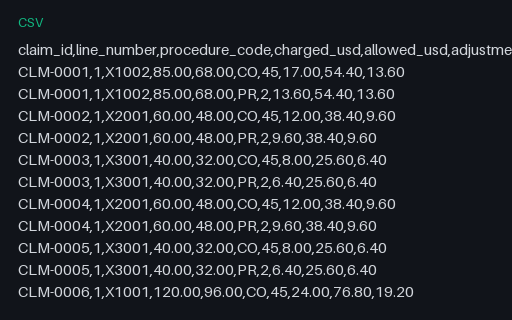
- csvJuniper Fitness and Clinic Administration: Remittance adjustment linesRemittance adjustment lines for Juniper Fitness and Clinic Administration. 35 rows, one per adjustment rather than one per service line, because a paid service line carries two adjustments and a denied one carries a single CO 97. Grouping by adjustment group gives 304.00 USD of CO write-offs and 175.20 USD of PR patient responsibility. Summing the charged column instead double counts, because charged repeats on both adjustment rows of a paid line.
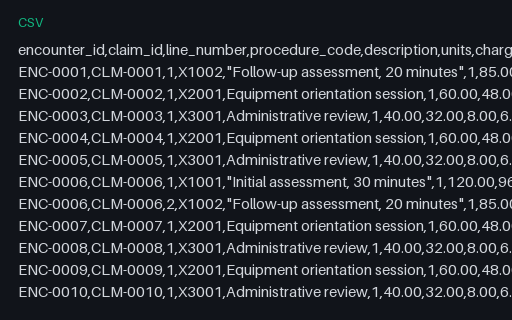
- csvJuniper Fitness and Clinic Administration: Service line detailService line detail for Juniper Fitness and Clinic Administration. All 18 service lines across the 16 encounters. Charges sum to 1,180.00 USD, which is the charge column of encounter-register.csv added, and grouping by claim_id reproduces every claim total exactly. This is the file the 837 service-line total has to agree with.
Generated by generation/industry_documents_two.py. Free for any use, no attribution required, license.