Fieldnote Learning Centre: Course capacity and outcome report
Course capacity and outcome report for Fieldnote Learning Centre. 3 courses, each seating 10 and holding 6 enrolments, so every course is at 60.00 percent with 4 seats free. pass_rate_of_completed divides passes by completions, not by enrolments, which is why COURSE-1 reports 60.00 percent from 3 passes out of 5 completions rather than out of 6 enrolments.
csv
text/csv
- Document Set
- education
- Industry
- education
- Source Kit
- education-training
- Synthetic
- true
- As Of
- 2026-09-08
- Rows
- 3
Binary csv: no in-browser preview. Download it above to open in a compatible application.
Specifications
- Document Set
- education
- Industry
- education
- Source Kit
- education-training
- Synthetic
- true
- As Of
- 2026-09-08
- Rows
- 3
- Capacity Each
- 10
- Enrolments
- 18
- Encoding
- UTF-8
Testing contract
Expected to pass- Scenario
- Group the enrolment export by course and recompute the capacity and outcome columns.
- Expected result
- All 3 rows reproduce: enrolled sums to 18, completed to 15 and passed to 9, and seats_available is capacity minus enrolled with no course oversubscribed. Each pass rate is passes over completions; every course carries exactly one incomplete enrolment, so dividing by enrolments instead reports 50.00 on every course rather than the 60.00 reported here.
What is a .csv file?
CSV (Comma-Separated Values) is a plain-text tabular format where rows are lines and fields are separated by commas, with quoting rules for values that contain delimiters, quotes, or newlines. It has no formal type system and depends on encoding and dialect conventions. It is the most portable format for tabular data exchange.
How to use this file
Use an example CSV to test parsers against quoting and embedded-delimiter edge cases, header handling, encoding detection, and import pipelines into databases or spreadsheets.
How to use this file for testing
“Fieldnote Learning Centre: Course capacity and outcome report” is a deterministic Novus Examples fixture for Data import. Realistic faker-generated datasets with documented schemas for testing import and ETL flows.
Documented properties for this file: 3 rows · UTF-8. Compare results against paired or grouped companions on this page when present (clean↔damaged, searchable↔scanned, or format twins) so scores stay reproducible across runs.
Download the file once, keep the path stable in CI or local scripts, and treat the spec table as the contract: dimensions, seeds, field lists, and roles are intentional. Corrupt or invalid samples are labelled as such, expect parsers to fail loudly rather than silently accept them.
Data fixtures document their exact quirks (delimiters, encodings, null handling, schema, and row counts) in the spec table. Point your parser or importer at the file and assert it handles the documented edge cases; clean and deliberately-messy siblings make before/after diffs straightforward.
Code examples
import pandas as pd

df = pd.read_csv("course-capacity-report.csv")
print(df.head())
print(df.dtypes)
Related files
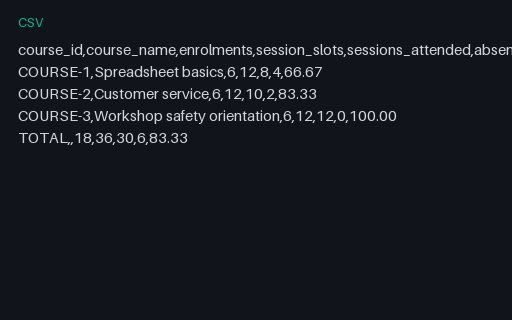
- csvFieldnote Learning Centre: Attendance summary by courseAttendance summary by course for Fieldnote Learning Centre. 3 courses and a TOTAL row. Attendance is uneven: 66.67 percent on Spreadsheet basics, 83.33 on Customer service and 100.00 on Workshop safety orientation, 83.33 overall. session_slots is enrolments times 2 on every row and sessions_attended plus absences equals it.
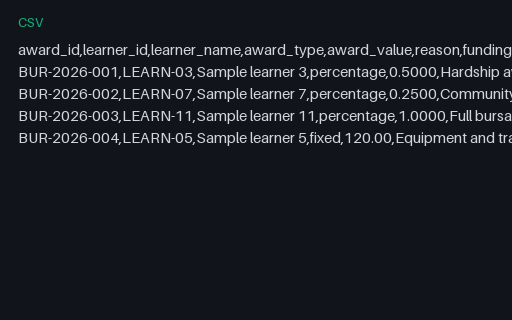
- csvFieldnote Learning Centre: Bursary award registerBursary award register for Fieldnote Learning Centre. 4 awards worth 807.50. Three are a percentage of the fee and apply to every enrolment the learner holds; one is a fixed 120.00 award and applies to that learner's earliest enrolment only, capped at the fee. award_value is a rate for a percentage award and an amount for a fixed one, which is why the column mixes 0.5000 with 120.00.
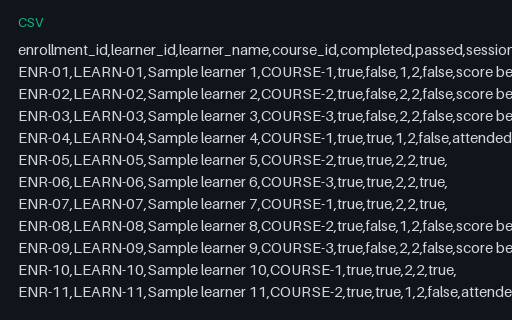
- csvFieldnote Learning Centre: Certificate eligibility with three conditionsCertificate eligibility with three conditions for Fieldnote Learning Centre. All 18 enrolments tested against three conditions: the enrolment is complete, the score reaches the pass mark, and both sessions were attended. 7 are eligible. 9 enrolments passed, so 2 passing learners are still ineligible on attendance alone: ENR-04 and ENR-11, each of whom attended 1 of 2 sessions. Every ineligible row names its reasons.
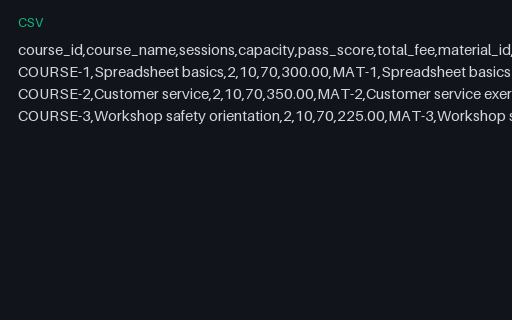
- csvFieldnote Learning Centre: Course catalogue with materialsCourse catalogue with materials for Fieldnote Learning Centre. 3 courses with their fee, capacity, pass score and the exercise material attached to each. material_characters is the exact length of the markdown exercise held against the course in the operating model, from 197 to 253 characters, so a content-length assertion has a real number to check.
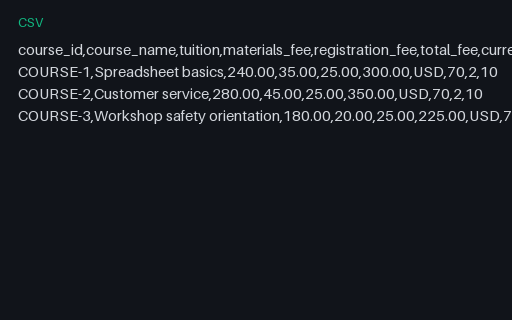
- csvFieldnote Learning Centre: Course fee scheduleCourse fee schedule for Fieldnote Learning Centre. 3 courses with the fee broken into tuition, materials and a flat 25.00 registration charge. The three components add up to total_fee on every row: 300.00, 350.00 and 225.00. Every course runs 2 sessions, seats 10 and passes at 70.
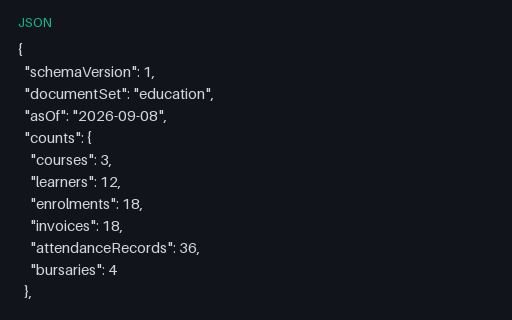
- jsonFieldnote Learning Centre: Education reconciliation assertionsEducation reconciliation assertions for Fieldnote Learning Centre. The six identities this set claims with the figure each must produce: 5250.00 of gross fees, 4442.50 net of bursary, 9 passes, 7 certificates, 18 results in both gradebook shapes and 2600.00 of scheduled instalments. It also records both deliberate defects and their exact size.
Generated by generation/industry_documents.py. Free for any use, no attribution required, license.