Juniper Workspace Cloud: Capitalisation table
Capitalisation table for Juniper Workspace Cloud. The 4 holdings split into nominal and premium with a total row. Only MEM-04 carries premium, 14,400.00 USD, because only the 2026-05-18 allotment was priced above nominal, at 0.25 against 0.01. The percentages are apportioned by largest remainder and sum to exactly 100.0000.
csv
text/csv
- Document Set
- corporate
- Industry
- software
- Source Kit
- saas-subscriptions
- Entity
- Juniper Workspace Cloud
- Synthetic
- true
- As Of
- 2026-09-08
Binary csv: no in-browser preview. Download it above to open in a compatible application.
Specifications
- Document Set
- corporate
- Industry
- software
- Source Kit
- saas-subscriptions
- Entity
- Juniper Workspace Cloud
- Synthetic
- true
- As Of
- 2026-09-08
- Rows
- 5
- Members With Premium
- 1
- Percent Total
- 100.0000
Testing contract
Expected to pass- Scenario
- Check that nominal plus premium equals amount paid on every row and in the total.
- Expected result
- Every row balances, three rows have zero premium, and the total row reads 6000.00 nominal plus 14400.00 premium equals 20400.00 paid.
What is a .csv file?
CSV (Comma-Separated Values) is a plain-text tabular format where rows are lines and fields are separated by commas, with quoting rules for values that contain delimiters, quotes, or newlines. It has no formal type system and depends on encoding and dialect conventions. It is the most portable format for tabular data exchange.
How to use this file
Use an example CSV to test parsers against quoting and embedded-delimiter edge cases, header handling, encoding detection, and import pipelines into databases or spreadsheets.
How to use this file for testing
“Juniper Workspace Cloud: Capitalisation table” is a deterministic Novus Examples fixture for Data import, CSV parsing. Realistic faker-generated datasets with documented schemas for testing import and ETL flows.
Documented properties for this file: 5 rows. Compare results against paired or grouped companions on this page when present (clean↔damaged, searchable↔scanned, or format twins) so scores stay reproducible across runs.
Download the file once, keep the path stable in CI or local scripts, and treat the spec table as the contract: dimensions, seeds, field lists, and roles are intentional. Corrupt or invalid samples are labelled as such, expect parsers to fail loudly rather than silently accept them.
Data fixtures document their exact quirks (delimiters, encodings, null handling, schema, and row counts) in the spec table. Point your parser or importer at the file and assert it handles the documented edge cases; clean and deliberately-messy siblings make before/after diffs straightforward.
Code examples
import pandas as pd

df = pd.read_csv("cap-table.csv")
print(df.head())
print(df.dtypes)
Related files
- csvJuniper Workspace Cloud: Meeting attendance registerMeeting attendance register for Juniper Workspace Cloud. 8 attendance rows across two board meetings. The attended column carries three values, true, false and in attendance, because the secretary attends without being a director and does not count towards the quorum. Both meetings met the quorum of two directors with two and three directors present.
- csvJuniper Workspace Cloud: Register of chargesRegister of charges for Juniper Workspace Cloud. Two charges, one satisfied and one outstanding. The outstanding floating charge secures 48,000.00 USD, which is the same principal as the loan facility in the banking set, so the two sets describe the same borrowing from the lender side and the borrower side.
- csvJuniper Workspace Cloud: Register of directors and secretariesRegister of directors and secretaries for Juniper Workspace Cloud. 5 officers of whom 4 are currently in office. One row has a resigned_on date of 2026-05-18 and currently_in_office false; the other four have an empty resigned_on. The same date is the board meeting that appointed the replacement, so the register and the minutes agree.
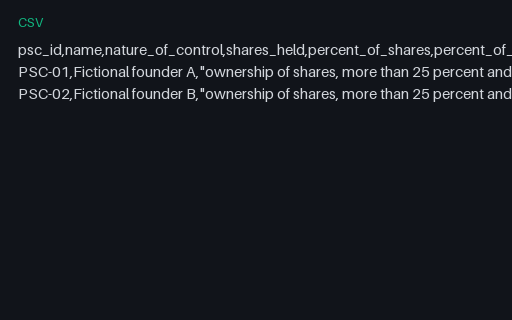
- csvJuniper Workspace Cloud: Register of persons with significant controlRegister of persons with significant control for Juniper Workspace Cloud. The two members holding more than 25 percent of the shares, with their holdings and percentages taken from the register of members. MEM-03 and MEM-04 hold 10.0000 percent each and are correctly absent, so a reader that expects every member to appear here will look for two rows that should not exist.
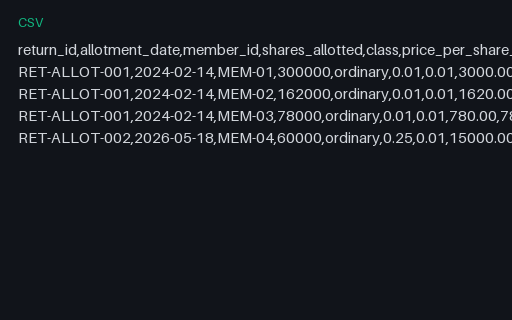
- csvJuniper Workspace Cloud: Share allotment returnShare allotment return for Juniper Workspace Cloud. 4 allotment rows across two returns. On every row consideration is shares times price and also equals nominal plus premium. The three founding rows are priced at nominal so their premium is 0.00; the 2026-05-18 row is priced at 0.25 against a 0.01 nominal, so 15,000.00 USD of consideration splits into 600.00 nominal and 14,400.00 premium.
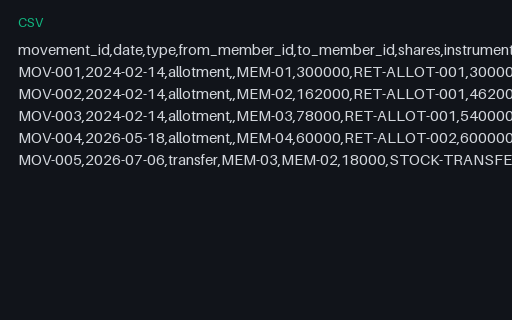
- csvJuniper Workspace Cloud: Shareholding movement historyShareholding movement history for Juniper Workspace Cloud. 5 movements in date order: four allotments that raise the shares in issue to 600,000 and one transfer of 18,000 shares from MEM-03 to MEM-02 that leaves the total unchanged. Replaying the movements from zero reproduces every holding in register-of-members.csv, including the certificate cancellations the transfer caused.
Generated by generation/industry_documents_two.py. Free for any use, no attribution required, license.