Pine Property Services: Site daily log
Site daily log for Pine Property Services. 9 daily entries, one for each completed work order, recording the crew, the labour hours and the weather. Hours total 27 and equal the labour hours the job cost report records against the same work orders. The four scheduled work orders have no log entry because no crew has attended them.
csv
text/csv
- Document Set
- construction
- Industry
- trades-property
- Source Kit
- trades-property
- Synthetic
- true
- As Of
- 2026-09-08
- Rows
- 9
Binary csv: no in-browser preview. Download it above to open in a compatible application.
Specifications
- Document Set
- construction
- Industry
- trades-property
- Source Kit
- trades-property
- Synthetic
- true
- As Of
- 2026-09-08
- Rows
- 9
- Labour Hours
- 27
- Encoding
- UTF-8
Testing contract
Expected to pass- Scenario
- Join the log to the job cost report and compare the hours per work order.
- Expected result
- All 9 work_order_id values resolve in job-cost-report.csv with status completed and identical labour hours, totalling 27. No log entry exists for a scheduled work order, so a productivity report built from the log covers completed work only.
What is a .csv file?
CSV (Comma-Separated Values) is a plain-text tabular format where rows are lines and fields are separated by commas, with quoting rules for values that contain delimiters, quotes, or newlines. It has no formal type system and depends on encoding and dialect conventions. It is the most portable format for tabular data exchange.
How to use this file
Use an example CSV to test parsers against quoting and embedded-delimiter edge cases, header handling, encoding detection, and import pipelines into databases or spreadsheets.
How to use this file for testing
“Pine Property Services: Site daily log” is a deterministic Novus Examples fixture for Data import. Realistic faker-generated datasets with documented schemas for testing import and ETL flows.
Documented properties for this file: 9 rows · UTF-8. Compare results against paired or grouped companions on this page when present (clean↔damaged, searchable↔scanned, or format twins) so scores stay reproducible across runs.
Download the file once, keep the path stable in CI or local scripts, and treat the spec table as the contract: dimensions, seeds, field lists, and roles are intentional. Corrupt or invalid samples are labelled as such, expect parsers to fail loudly rather than silently accept them.
Data fixtures document their exact quirks (delimiters, encodings, null handling, schema, and row counts) in the spec table. Point your parser or importer at the file and assert it handles the documented edge cases; clean and deliberately-messy siblings make before/after diffs straightforward.
Code examples
import pandas as pd

df = pd.read_csv("daily-log.csv")
print(df.head())
print(df.dtypes)
Related files
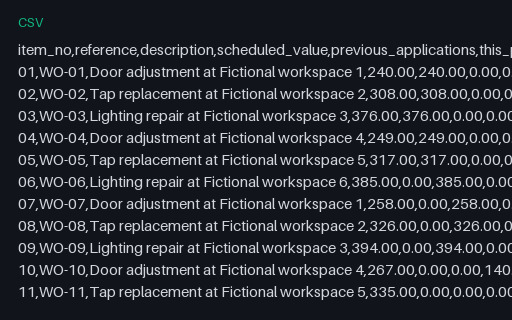
- csvPine Property Services: Application for payment continuation sheetApplication for payment continuation sheet for Pine Property Services. 12 contract items, 2 change order lines and a TOTAL row, in the shape of an AIA G703 continuation sheet. Scheduled values total 4113.00; 1490.00 was certified on the previous application, 1618.00 is claimed this period and 140.00 is materials stored but not installed, giving 3248.00 completed and stored. Retainage is 10 percent of each line and totals 324.80.
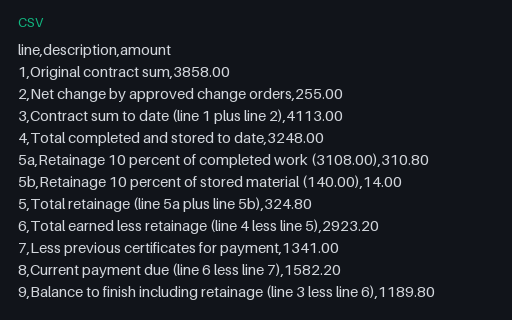
- csvPine Property Services: Application for payment summaryApplication for payment summary for Pine Property Services. The nine numbered lines of an AIA G702 style application. Contract sum 3858.00 plus 255.00 of change orders gives 4113.00; 3248.00 is completed and stored, retainage of 324.80 splits 310.80 on work and 14.00 on stored material, and after 1341.00 of previous certificates the current payment due is 1582.20.
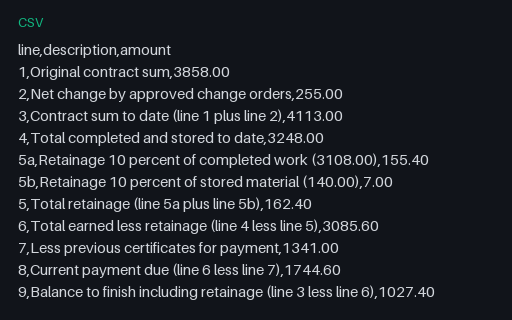
- csvPine Property Services: Application for payment whose retainage was withheld at the wrong rateApplication for payment whose retainage was withheld at the wrong rate for Pine Property Services. The same nine lines as application-for-payment-002-summary.csv, but lines 5a and 5b were computed at 5 percent while their own descriptions still read 10 percent. Retainage reads 162.40 instead of 324.80, so the current payment due on line 8 reads 1744.60 against the correct 1582.20, 162.40 too much.
- csvPine Property Services: Approved change order registerApproved change order register for Pine Property Services. 2 approved change orders: an addition of 420.00 for extra door hardware and a credit of -165.00 for deleted lighting scope, a net 255.00. The running contract sum moves from 3858.00 to 4113.00, which is line 3 of the payment application. A credit change order is a negative amount, not a separate document type.
- csvPine Property Services: Completion inspection registerCompletion inspection register for Pine Property Services. 9 inspections, one for each completed work order. 8 passed and 1 needs a follow-up, INSPECT-6 against WO-06. follow_up_required is derived from result and agrees with it on every row. Every note carries the standing caveat that these are operational checks, not regulated certificates.
- jsonPine Property Services: Construction reconciliation assertionsConstruction reconciliation assertions for Pine Property Services. The eight identities this set claims with the figure each must produce: a 3858.00 contract sum moving to 4113.00, 3248.00 completed and stored, 324.80 retained, 1582.20 due, and a job cost variance of 1020.00. It also records the 162.40 size of the deliberate defect.
Generated by generation/industry_documents.py. Free for any use, no attribution required, license.