Alder Books Reconciliation: General ledger in the European CSV dialect
General ledger in the European CSV dialect for Alder Books Reconciliation. The same 66 ledger lines with a semicolon delimiter, decimal commas, dot thousands separators and dd/mm/yyyy posting dates. This is the shape a ledger export from a European accounting package arrives in.
csv
text/csv
- Document Set
- accounting
- Industry
- finance
- Source Kit
- accounting-reconciliation
- Synthetic
- true
- As Of
- 2026-09-08
- Rows
- 66
Binary csv: no in-browser preview. Download it above to open in a compatible application.
Specifications
- Document Set
- accounting
- Industry
- finance
- Source Kit
- accounting-reconciliation
- Synthetic
- true
- As Of
- 2026-09-08
- Rows
- 66
- Delimiter
- semicolon
- Decimal Mark
- comma
- Date Format
- dd/mm/yyyy
- Encoding
- UTF-8
Testing contract
Expected to pass- Scenario
- Import the ledger with the European dialect configured and check that it still balances.
- Expected result
- Read with a semicolon delimiter and a comma decimal mark, the 66 lines give debits and credits of 22464.00 each, the same totals as general-ledger-export.csv.
What is a .csv file?
CSV (Comma-Separated Values) is a plain-text tabular format where rows are lines and fields are separated by commas, with quoting rules for values that contain delimiters, quotes, or newlines. It has no formal type system and depends on encoding and dialect conventions. It is the most portable format for tabular data exchange.
How to use this file
Use an example CSV to test parsers against quoting and embedded-delimiter edge cases, header handling, encoding detection, and import pipelines into databases or spreadsheets.
How to use this file for testing
“Alder Books Reconciliation: General ledger in the European CSV dialect” is a deterministic Novus Examples fixture for Data import. Realistic faker-generated datasets with documented schemas for testing import and ETL flows.
Documented properties for this file: 66 rows · UTF-8. Compare results against paired or grouped companions on this page when present (clean↔damaged, searchable↔scanned, or format twins) so scores stay reproducible across runs.
Download the file once, keep the path stable in CI or local scripts, and treat the spec table as the contract: dimensions, seeds, field lists, and roles are intentional. Corrupt or invalid samples are labelled as such, expect parsers to fail loudly rather than silently accept them.
Data fixtures document their exact quirks (delimiters, encodings, null handling, schema, and row counts) in the spec table. Point your parser or importer at the file and assert it handles the documented edge cases; clean and deliberately-messy siblings make before/after diffs straightforward.
Code examples
import pandas as pd

df = pd.read_csv("general-ledger-eu-dialect.csv")
print(df.head())
print(df.dtypes)
Related files
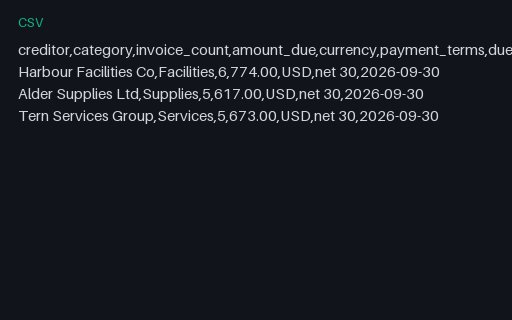
- csvAlder Books Reconciliation: Aged creditors summaryAged creditors summary for Alder Books Reconciliation. The 3 suppliers behind the 16 operating payments, grouped by expense category. The amounts due are 774.00, 617.00, 673.00 and they sum to 2064.00, which is the total of the three actual columns on the budget report.
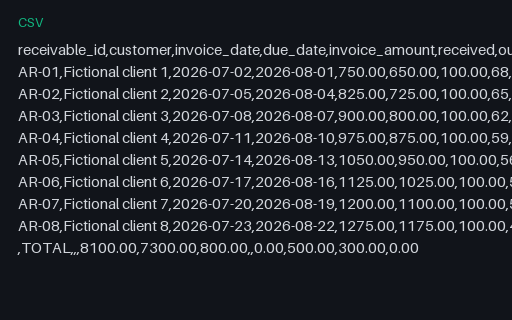
- csvAlder Books Reconciliation: Aged debtors reportAged debtors report for Alder Books Reconciliation. 8 open receivables aged at 2026-09-08, each with 100.00 outstanding against an invoice of between 750.00 and 1275.00. The ageing buckets hold 0.00 current, 500.00 at 31 to 60 days and 300.00 at 61 to 90 days, summing to 800.00, the receivables line of the trial balance.
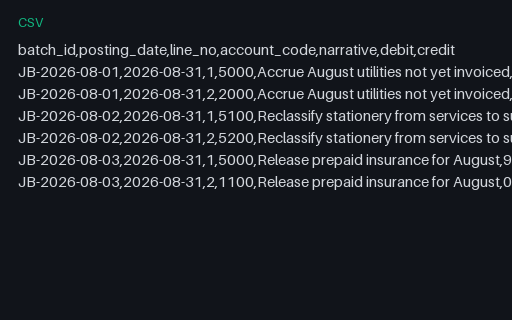
- csvAlder Books Reconciliation: Balanced manual journal batchBalanced manual journal batch for Alder Books Reconciliation. 3 month-end journals of 2 lines each, 6 lines in total: an accrual, a reclassification and a prepayment release. Each batch_id balances on its own and the batch as a whole posts 339.75 of debits and the same of credits.
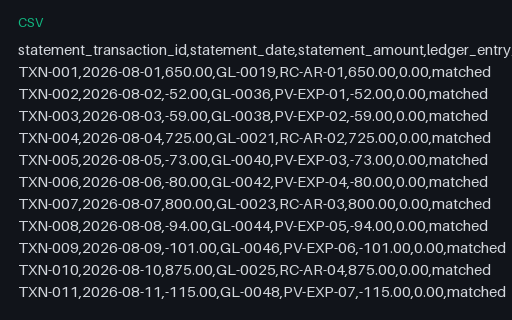
- csvAlder Books Reconciliation: Bank reconciliationBank reconciliation for Alder Books Reconciliation. All 24 statement transactions matched one for one to a cash-account ledger line, with a difference column that is 0.00 on every row. There are no unpresented items and no deposits in transit, so the book balance 10236.00 equals the statement balance 10236.00 and the reconciling difference is 0.00.
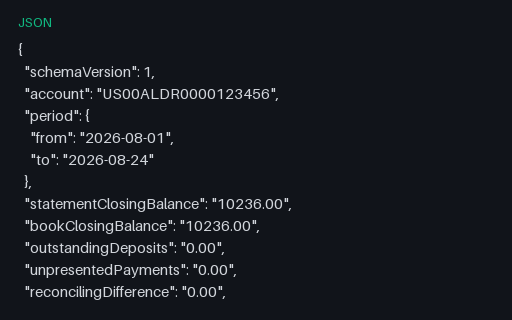
- jsonAlder Books Reconciliation: Bank reconciliation JSONBank reconciliation JSON for Alder Books Reconciliation. The same 24 matches as bank-reconciliation.csv with the reconciliation summary at the top: statement closing 10236.00, book closing 10236.00, nothing outstanding or unpresented and a reconciling difference of 0.00.
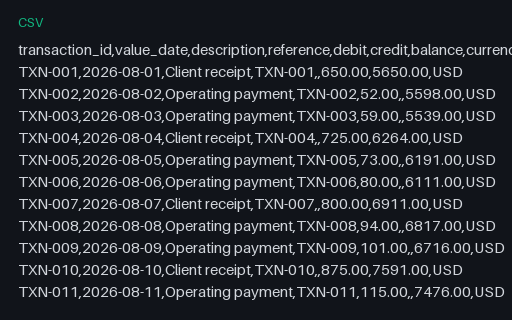
- csvAlder Books Reconciliation: Bank statement CSVBank statement CSV for Alder Books Reconciliation. 24 transactions from 2026-08-01 to 2026-08-24 in separate debit and credit columns, with a running balance. The statement opens at 5000.00 and closes at 10236.00; 8 credits total 7300.00 and 16 debits total 2064.00.
Generated by generation/industry_documents.py. Free for any use, no attribution required, license.